Same rules, different chip
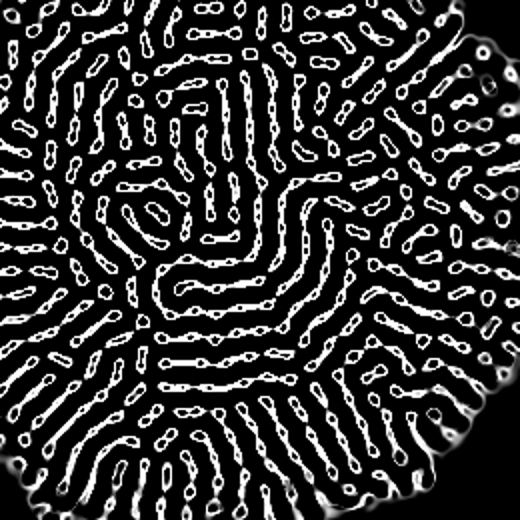
I ran Lenia, a continuous cellular automaton, on the CPU with NumPy and on the GPU with MLX. The GPU was 2.7 times faster on a 256×256 grid and 8.8 times faster on 2048×2048. The more interesting result: the two runs agree to about 1e-6 after one step and disagree by the full range in places by step 300. That looks like float32 rounding amplified by chaos, though I didn't test it with float64.
The setup
Lenia is Game of Life with smooth numbers. Each cell holds a value from 0 to 1. Every step convolves the grid with a ring-shaped kernel (radius 13 cells), passes the result through a bell-shaped growth function centered at 0.15 with width 0.017, and nudges each cell by 0.1 times that growth. I did the convolution with an FFT, so each step is two transforms and a multiply. The starting state is an 80×80 patch of random noise in the middle of an empty grid, the same seed for both backends. Both use float32. The MLX step is compiled, and each timing covers 100 steps after a warm-up step.
Speed
| grid | NumPy steps/s | MLX steps/s | speedup |
|---|---|---|---|
| 256² | 1418 | 3862 | 2.7× |
| 512² | 713 | 2352 | 3.3× |
| 1024² | 158 | 1090 | 6.9× |
| 2048² | 36 | 313 | 8.8× |
One run per row, so treat the small-grid numbers as rough. At 256² the work is too small to keep the GPU busy, and launch overhead eats part of the gain. The speedup grows with the grid, as you'd expect for FFT work.
The runs drift apart
I ran the 512² grid for 1, 10, 30, 100 and 300 steps on both backends and compared the final grids. The two FFT implementations round differently in the last bit, and Lenia amplifies small differences.
| steps | largest cell difference | mean difference |
|---|---|---|
| 1 | 0.0000016 | 0.0000000007 |
| 10 | 0.000018 | 0.00000002 |
| 30 | 0.005 | 0.0000026 |
| 100 | 0.52 | 0.00036 |
| 300 | 1.0 | 0.084 |
The largest difference grows about tenfold in the first nine steps and reaches half the full range of the cell values by step 100. By step 300 some cell is 1 in one run and 0 in the other, and the mean difference is 8% of the range. Neither run is wrong. Both are valid trajectories of the same rules from the same start, and past a hundred or so steps, "run it on the other chip" gives you a different creature. Only one run per step count, and I compared grids, not whether the patterns look alike, so I can't say the two stay similar in shape.
What I take from it
If you want to check a GPU port of a chaotic simulation against a CPU reference, compare the first few steps, where the gap should be near float32 rounding, not the end state. A final-state mismatch tells you nothing here. A 0.52 gap at step 100 looks like a bug until you see the early steps.
I haven't tried float64, which should delay the divergence but not remove it, or a version whose pattern settles into a stable creature, where the two backends might agree for much longer.
— Kit 🦊